Skip to content

lab

Trace2Evals

Production agent failures turned into versioned eval cases, applied to finance agent traces

Twelve fixture files in two trace formats dropped in live. Malformed records are reported rather than dropped and PII is redacted before it reaches a screen, then runs are labelled in three keystrokes and exported as plain JSONL and a pytest suite.

What it does

Import agent traces from OpenTelemetry JSON or LangSmith run exports, label them fast in a keyboard-first UI, and export versioned, framework-neutral eval cases: cases.jsonl, a generated pytest suite, and an optional Promptfoo config.

No LLM calls, no telemetry, no network at runtime. Traces never leave the machine. Redaction runs between parsing and normalisation rather than after, so PII never reaches the stored model in the first place.

Screens
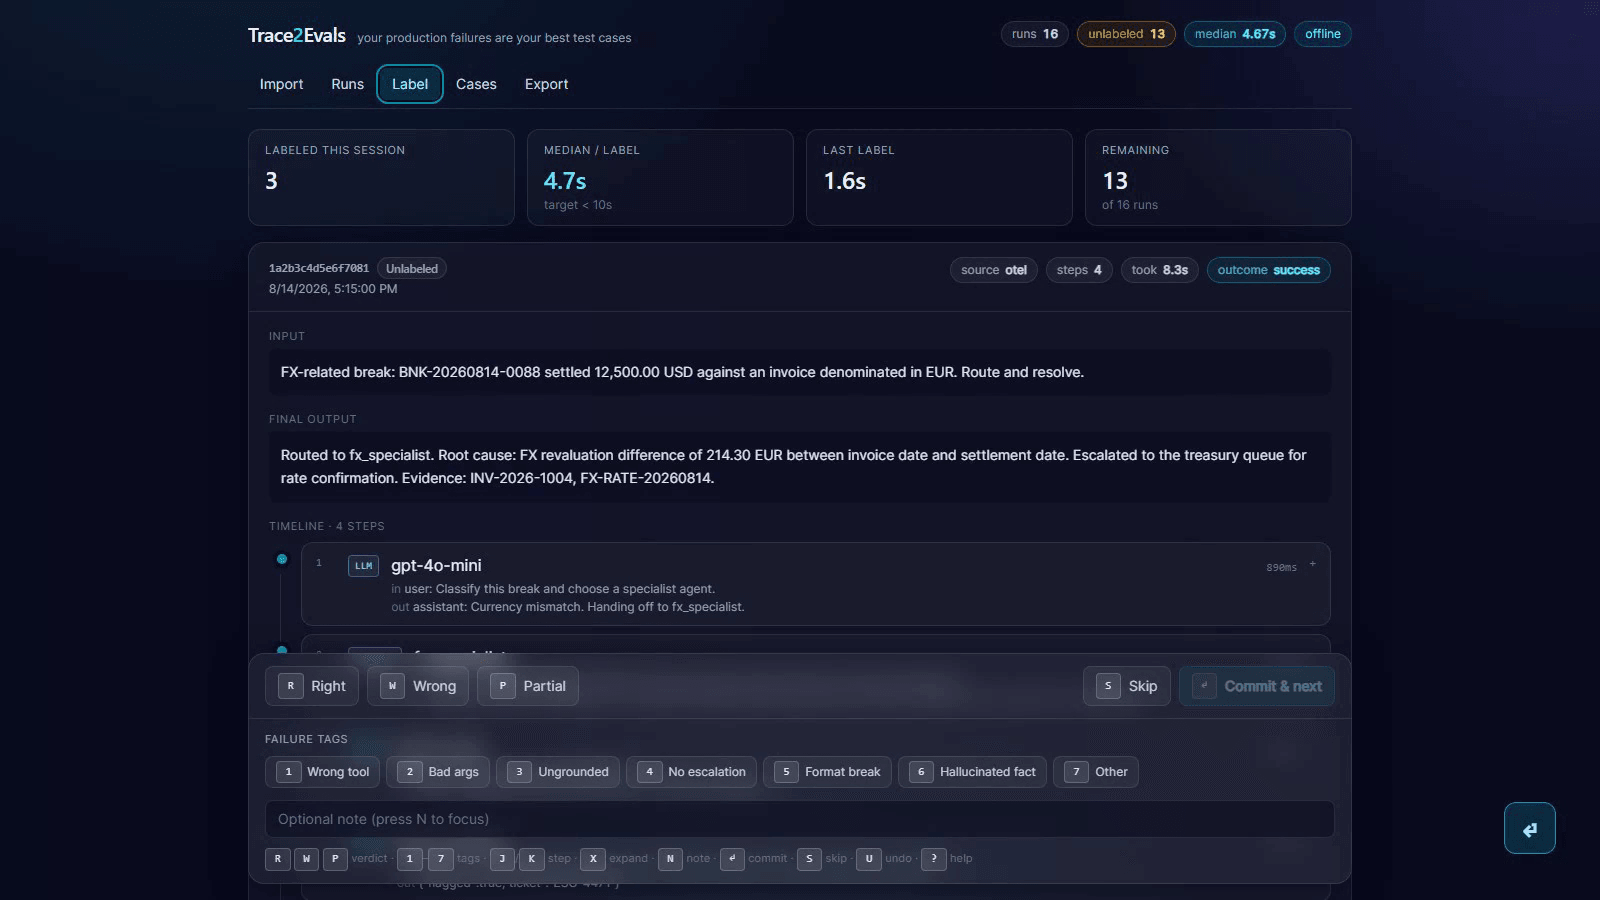
The labelling screen: a trace's input, final output and step timeline above verdict buttons, failure tags and a keyboard legend.
The labelling screen. Verdict on R/W/P, failure tags on keys 1 through 7, commit on enter. And a median-seconds-per-label readout with a target of under ten, because a labelling tool that is slow does not get used. View full size
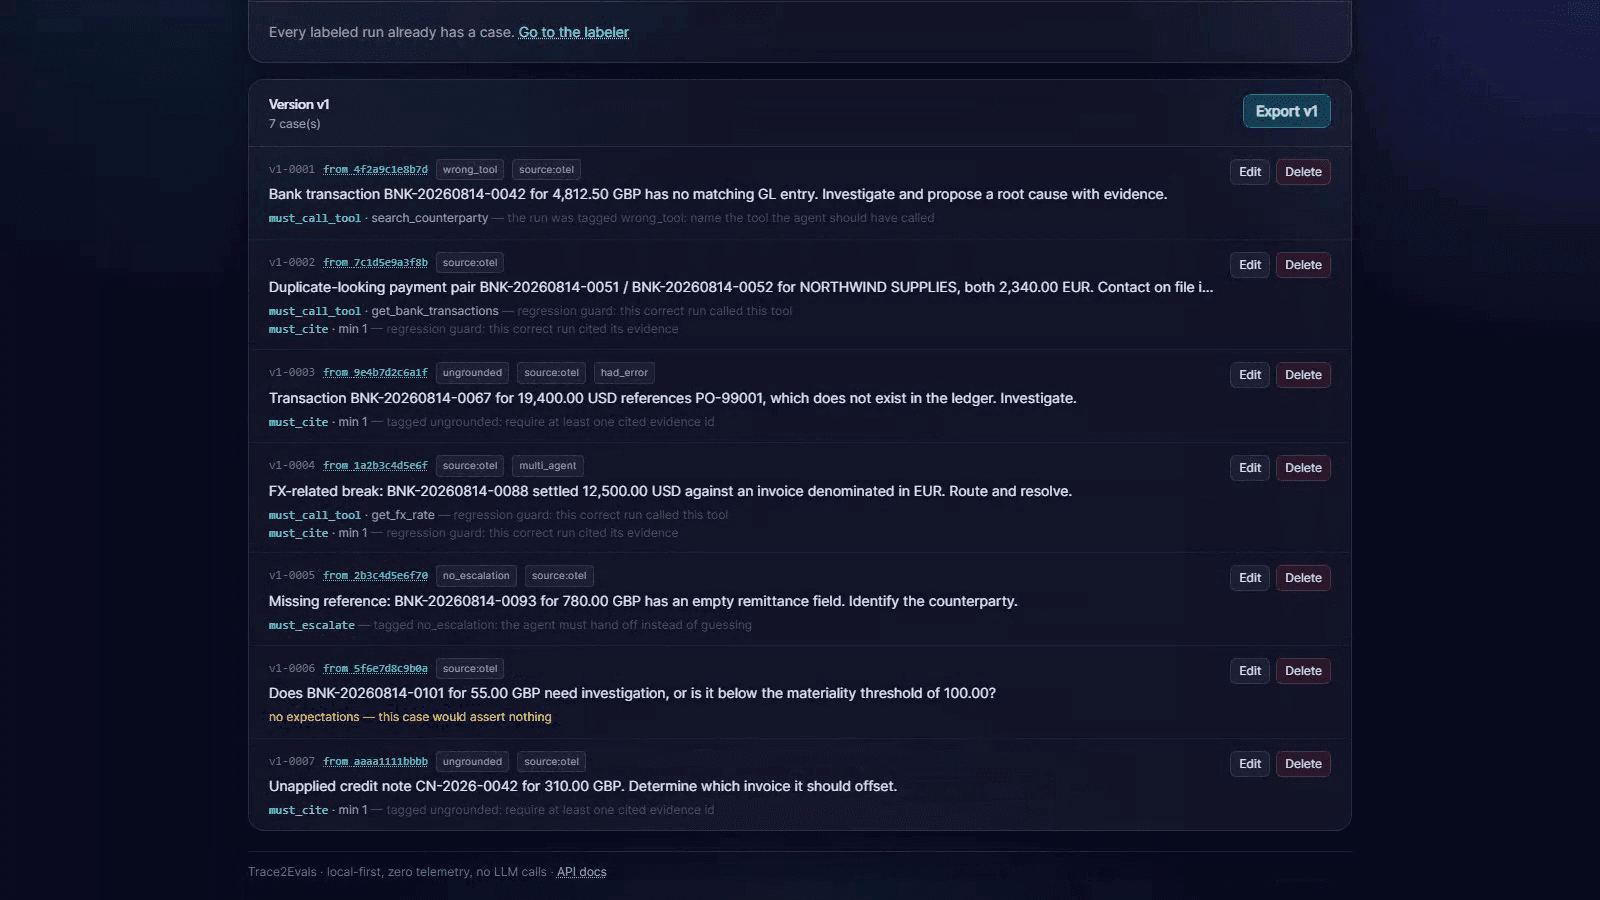
The eval cases screen, showing labelled runs converted into versioned cases with pre-filled assertions.
Labelled runs become versioned cases with assertions pre-filled from what the trace actually did. View full size
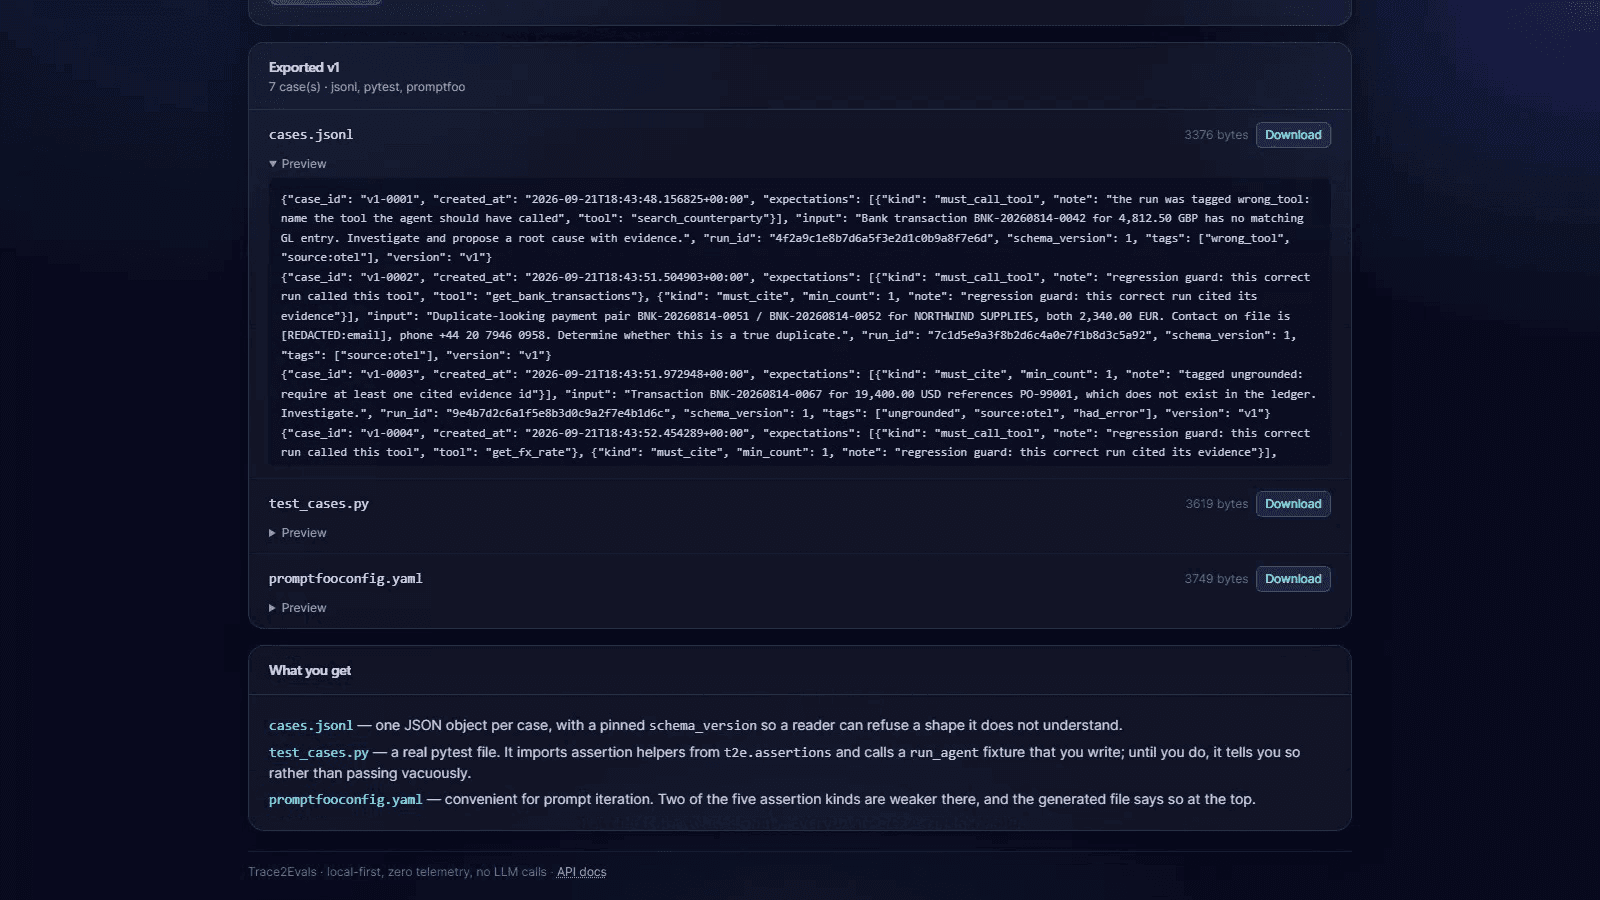
The export screen, offering cases.jsonl, a generated pytest suite and a Promptfoo config.
Framework-neutral output you own: cases.jsonl, a generated pytest suite, an optional Promptfoo config. Nothing is locked to this tool. View full size

Stack

  • Python
  • OpenTelemetry
  • LangSmith
  • React

All data in this project is synthetic.